

China’s first Tibetan-language LLM DeepZang upgraded for applications including grassroots governance
(Photo: VCG)
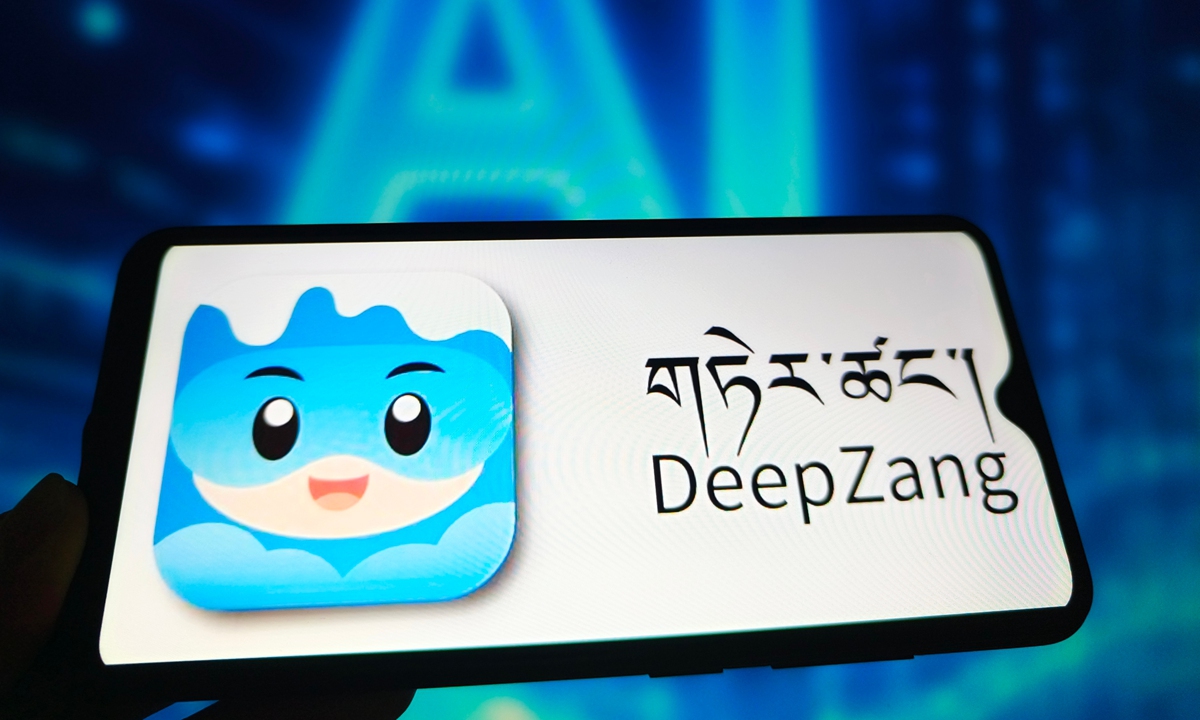
DeepZang, China's first Tibetan large language model (LLM), has begun a new round of upgrades to enhance Tibetan-language artificial intelligence (AI) technology and advance the deployment of multilingual simultaneous interpretation, aiming to further integrate the model into public services, education and healthcare, cultural tourism development, grassroots governance and other application scenarios, according to recent media reports.
Researchers, university and company representatives gathered in Hohhot, North China's Inner Mongolia Autonomous Region on Monday for a meeting on upgrading DeepZang and advancing its simultaneous-interpretation technology, discussing ethnic-language corpora, low-resource language model training and cross-lingual innovation, laying the groundwork for joint technological breakthroughs and the commercialization of research results, according to chinanews.com.
Tibetan has long presented a challenge for natural language processing, given its complex linguistic structure, diverse dialects and limited high-quality data. Improving the accuracy and versatility of Tibetan-language AI has thus remained a major research priority.
Since its launch, DeepZang has advanced Tibetan-language AI through improvements in multi-dialect adaptation, semantic recognition and offline applications. It has helped the technology evolve from being "basically usable" to more accurate and user-friendly, filling several technological gaps in the industry and helping improve China's technological framework for AI in ethnic minority languages.
The LLM was trained on nearly 70 million high-quality Tibetan-Chinese parallel corpus data and more than 30,500 hours of audio covering three major Tibetan dialects, the Xinhua News Agency reported. It supports AI conversations, real-time translation and speech-to-text in Tibetan, Chinese and English.
Tenzin Norbu, founder of CHOKNOR, which developed DeepZang, said that the development of AI technologies for China's various ethnic minority languages faces similar challenges related to limited resources, which underscores the importance of cross-regional and cross-lingual collaboration.
Going forward, the research team will continue to upgrade Tibetan-language AI and expand its applications, using technology to support interethnic exchanges and promote digital and intelligent development in ethnic minority regions.